 Capital de Tokens
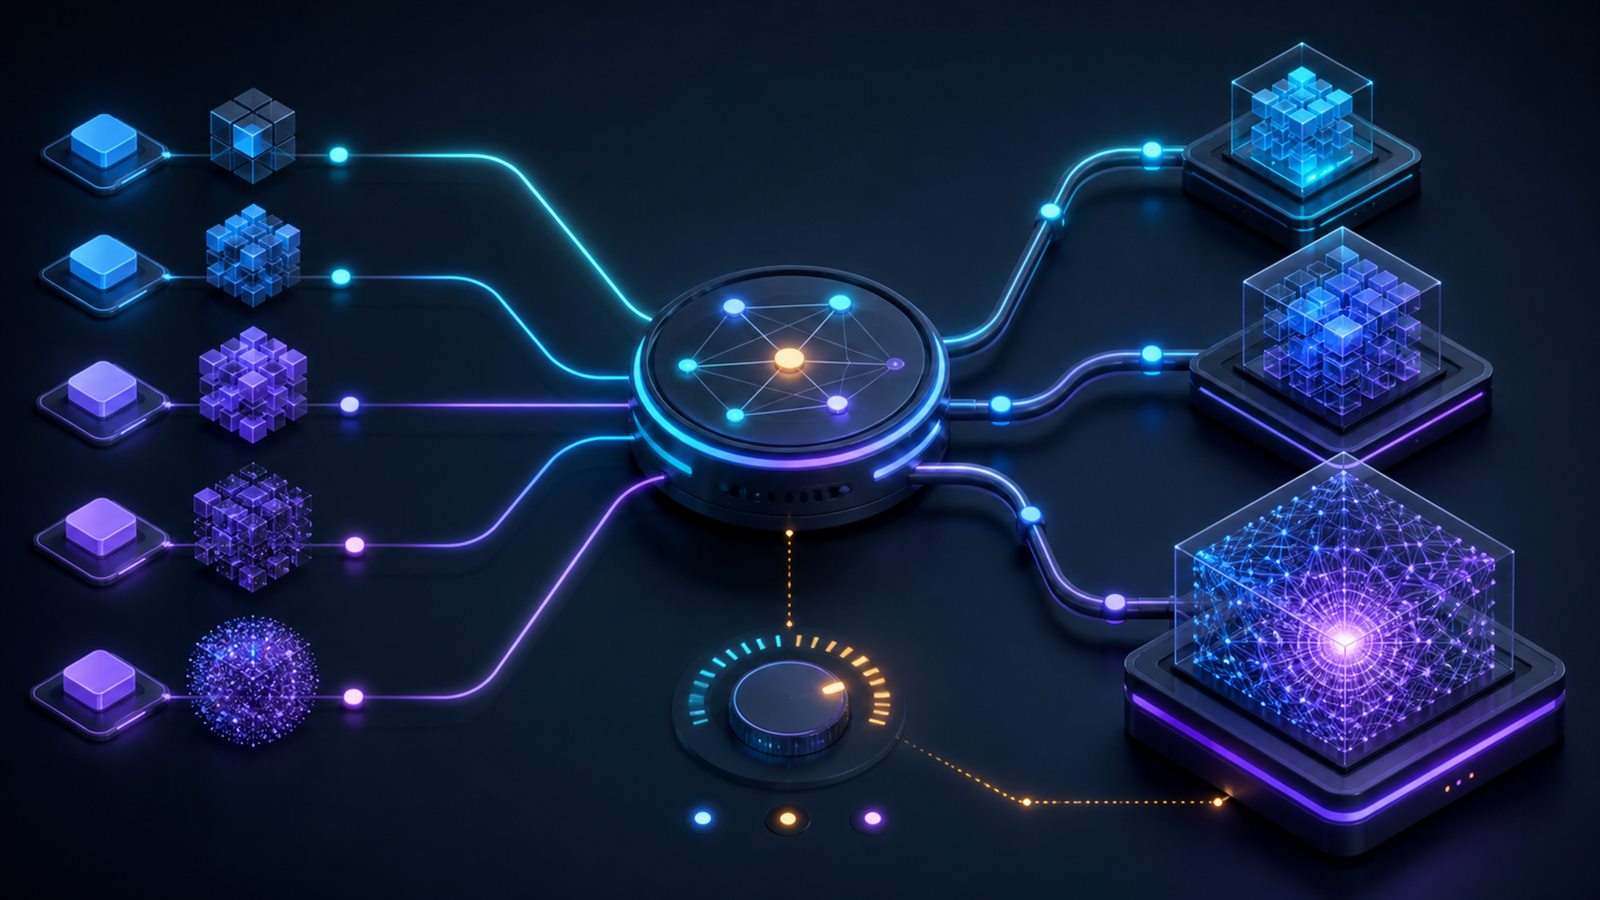
Cursor Router: choosing the right model for each task without overspending
When we use a coding agent, we often make a fairly primitive decision:
pick a model
     ↓
use it for everything
The problem is that not every task needs the same level of intelligence, latency, or cost.
Making a commit, renaming something, or running a simple command may be routine work. Understanding a large codebase, planning a refactor, or debugging a difficult visual issue may justify a much more expensive model.
Cursor is trying to turn that intuition into a routing system learned from real production traffic.
In its technical explanation of Cursor Router, the company describes an architecture that breaks the decision into three questions:
1. How complex does this task appear to be?
2. If it is complex, what kind of task is it?
3. Which model gives the best expected gain within budget?
The important idea is not simply that “Auto picks a model.”
What is interesting is that Cursor treats model selection as a problem of prediction + classification + economic optimization.
The problem: using the best model for everything is also a bad strategy
A simple strategy would send every request to the most capable frontier model available.
That maximizes potential capability, but wastes money on easy work.
simple request
     ↓
frontier model
     ↓
correct answer
     ↓
but at frontier price
The opposite strategy does not work well either:
difficult request
     ↓
cheap model
     ↓
corrections
     ↓
retries
     ↓
more tokens + more time
So the real problem is not minimizing the price of one call.
It is minimizing something closer to:
total cost
+
failure probability
+
retries
+
user friction
A cheap model that forces repeated attempts can end up being operationally more expensive than a stronger model used once.
Cursor Router tries to find that balance automatically.
First piece: learn from real work, not only benchmarks
Cursor starts with an interesting decision: the router is not trained only on synthetic benchmarks.
The company built its dataset from hundreds of thousands of turns of real developer traffic, while respecting users’ privacy and retention settings.
Each example contains the signals available before routing and two important outcomes:
- performance;
- cost.
But measuring “performance” in a coding agent is not trivial.
Cursor uses what the user does next as an indirect signal.
For example:
agent responds
      ↓
user moves to another task
      ↓
positive signal
While:
agent responds
      ↓
user corrects / asks for changes again
      ↓
negative signal
That turns normal product usage into feedback for the router.
It is not the same as formally proving that an answer is correct, but it has a major advantage: it reflects the work developers are actually trying to do.
Compass: predicting when a task deserves a more expensive model
The first Router decision is made by a component called Compass.
Compass produces a continuous score between 0 and 1 that Cursor uses as a proxy for complexity.
The intuition is straightforward.
Easy tasks are more likely to be completed without corrections.
Difficult tasks are more likely to trigger follow-ups, changes, and additional instructions.
Conceptually:
                 Compass
request ───────────┬───────────
                  │
             score 0..1
                  │
          ┌───────┴────────┐
          │                │
        low              high
          │                │
efficient model      evaluate frontier
Cursor reports that turns Compass considered easiest ended with a positive performance signal about 96% of the time, while the hardest end of the distribution was around 71%.
That score allows the system to move a threshold τ depending on the product objective.
score < τ
→ efficient model

score ≥ τ
→ task router
Changing τ directly changes the economics of the system.
A threshold that keeps more traffic on the cheap model reduces cost.
One that escalates more requests to frontier models buys more potential quality.
That is the Router’s first control knob.
Second piece: no model wins at everything
Once Compass decides that a task deserves more capability, another question remains:
Which model?
Cursor says it observed something that is becoming increasingly obvious in multi-model systems: different models have different strength profiles.
To represent this, Cursor classifies work along three dimensions.
1. Domain
Where the work happens.
For example:
- backend;
- frontend;
- database schemas.
2. Task
What the developer is trying to accomplish.
For example:
- fix a bug;
- run commands;
- write tests;
- plan an implementation.
3. Modifiers
Characteristics that cut across domains but can change which model performs best.
For example:
- tightly bounded edits;
- product questions;
- visually heavy changes.
The result can look like a composite label:
domain: frontend
task: debugging
modifier: visual-heavy
That taxonomy lets the system stop asking:
What is the best model?
And instead ask:
What is the best model for this kind of work?
The strength map Cursor observed
According to Cursor’s published results, different models excel in different categories.
In its traffic:
- Grok offered strong cost/performance for routine work, including Git commands and general database operations;
- Sol stood out for planning and codebase comprehension, along with several implementation tasks;
- Opus performed well on execution-heavy work, including DevOps, database queries, and performance optimization;
- Fable showed strengths in debugging and difficult visual implementation.
The architectural conclusion matters more than the exact ranking.
Models change quickly.
The durable idea is to maintain a map:
                    task classes
                         │
         ┌───────────────┼───────────────┐
         │               │               │
      model A          model B         model C
      strong here      strong there    better cost
The router does not need to marry one provider forever.
It needs to continuously learn where each model creates enough value to justify its cost.
Third piece: do not route on tiny differences
An aggressive router can make another mistake: switching models every time it detects a tiny or statistically uncertain advantage.
Cursor tries to avoid that with an eligibility rule.
A candidate model is considered only when the observed evidence for that category clears a one-sided threshold that Cursor describes approximately as 75% confidence that the improvement over the efficient model is real.
That creates a kind of indifference region:
frontier model looks 0.2% better
→ weak evidence
→ not worth switching

frontier model shows consistent advantage
→ eligible candidate
This matters because routing has secondary costs too:
- cache misses;
- latency differences;
- behavioral variation;
- higher token prices;
- more operational complexity.
The right question is not whether another model can be better.
It is whether it is better enough to justify the switch.
Then the budget enters
Once candidate models are identified, Cursor does not simply choose the one with the highest score.
It uses an optimizer that searches for the routing mix with the largest expected performance gain subject to an average cost-per-turn budget.
Conceptually:
maximize
    expected quality

subject to
    average cost ≤ budget
That turns model selection into something similar to resource allocation in infrastructure.
We are no longer asking:
which model is best?We are asking:
where does each additional dollar
produce the largest expected improvement?
That distinction explains why Cursor can expose multiple modes on top of the same Router.
Cost, Balance, and Intelligence are policies, not models
In Cursor’s current interface, Auto exposes three objectives:
- Cost;
- Balance;
- Intelligence.
They are not necessarily three different models.
They are three positions on the cost-quality curve.
Think of it like this:
low cost                                    maximum quality
   │                                              │
   ├──── Cost ───── Balance ───── Intelligence ───┤
The implementation can vary two large parameters:
Compass threshold
+
task-router budget
Balance keeps more traffic on the efficient path and gives the router a smaller budget for escalation.
Intelligence allows more spending when the expected performance gain justifies it.
The user does not have to manually choose between four providers on every turn.
The user chooses an economic policy.
The router handles the detail.
The published results are effectively a Pareto curve
Cursor currently reports that Auto Intelligence delivers above Fable-level user satisfaction at 68% lower cost, while Auto Balance outperforms Opus 4.8 at 41% lower cost and with a further 3% increase in user satisfaction in the company’s published comparison.
Beyond the exact numbers, the objective is what matters:
more quality
   ↑
   │           frontier model
   │        ●
   │     ● router
   │  ●
   └────────────────────────→ cost
The router tries to push the system outward on the Pareto frontier:
- similar quality for less money;
- or more quality at a similar cost.
That is a much more useful way to evaluate routing than simply counting how often it selected “the smartest model.”
The detail many routers miss: switching models can break cache efficiency
The cost of a multi-model system does not depend only on nominal token prices.
Suppose a long conversation already has context cached with one provider.
Switching models can produce:
model A
cached context ✅
      ↓
router switches to model B
      ↓
cache miss
      ↓
reprocess context
      ↓
additional cost
Cursor says it trained and evaluated its router while accounting for these effects, including cache misses caused by model switches.
That matters because a router that ignores caching can look excellent in a spreadsheet and become more expensive in production.
The real economics are:
model price
+
actual tokens
+
cache behavior
+
retries
+
latency
+
quality achieved
Not only dollars per million tokens.
This actually looks like a scheduler
There is a useful way to interpret Cursor Router.
It is not merely an LLM selector.
It is a scheduler for cognitive capacity.
In traditional infrastructure we already do something similar:
small job      → small resource
heavy job      → large resource
GPU workload   → specialized node
memory-heavy   → memory-optimized machine
Cursor is trying to apply equivalent logic to reasoning:
simple commit           → efficient model
complex plan            → planning-strong model
heavy DevOps            → execution-strong model
visual UI/debugging     → visual-strong model
That suggests the future of agentic platforms may look less like:
my agent uses model XAnd more like:
my agent has access to a pool of models
and a policy decides which one each step deserves
Model selection is becoming part of the control plane
A serious agentic system already makes decisions about:
which tool to use
which permissions to grant
how much context to load
when to execute in parallel
when to request approval
when to retry
when to stop
Model routing adds another one:
how much cognitive capacity to buy for this stepThat makes the model router part of the agent’s control plane.
A future architecture might look like:
                   Agent Control Plane
                          │
        ┌─────────────────┼──────────────────┐
        │                 │                  │
   task planner       tool router       model router
        │                 │                  │
        │                 │          ┌───────┼───────┐
        │                 │        cheap    Sol    Opus/Fable
        │                 │
        └──────── execution / verification ─────────┘
The model stops being the whole platform.
It becomes an interchangeable resource inside a larger platform.
But there is a warning: satisfaction is not the same as correctness
Cursor’s approach also has limitations worth understanding.
If reward is approximated from what the user does next, some situations are ambiguous.
For example:
user accepts responsecan mean:
- it was correct;
- it looked correct;
- the user did not notice the mistake;
- further correction was not worth the effort.
And:
user asks for another changecan mean:
- the response failed;
- the task simply evolved;
- the user changed their mind.
That is why production feedback is extremely valuable, but it does not remove the need for:
- independent evals;
- tests;
- execution signals;
- result verification;
- latency and cost metrics;
- A/B experiments.
The Router is a statistical system, not a proof of correctness.
Another challenge: the frontier changes too quickly
A router trained today can become stale quickly.
Every few weeks we get:
- new models;
- new versions;
- pricing changes;
- different context windows;
- better tool-use behavior;
- coding improvements;
- latency shifts.
Cursor has already added new models to the routing mix after launch and says it wants the router to evolve continuously with those changes.
That forces us to think of routing as a living system:
new model
    ↓
evaluation
    ↓
controlled traffic
    ↓
measure by category
    ↓
update strength map
    ↓
re-optimize policy
The competitive advantage is no longer only access to the best model.
It may also be learning faster when to use it.
The larger lesson: model routing is a systems problem
For a long time, LLM routing was discussed as if it were a simple if statement:
if task_is_hard:
    use_expensive_model()
else:
    use_cheap_model()
Cursor is showing a much more mature version.
We need to combine:
request signals
+
recent history
+
estimated complexity
+
task type
+
model strengths
+
statistical confidence
+
budget
+
cache behavior
+
real production feedback
That is no longer a prompt feature.
It is an infrastructure layer.
And we will likely see more agentic systems evolve in this direction.
The future may be “model-less” from the user’s point of view
Today we still ask:
Should I use Sol, Opus, Grok, or Fable?
But that may be a transitional stage.
As routing improves, the interface could collapse into something more like:
minimize cost
balance both
maximize quality
The system would choose the rest dynamically.
It is the same abstraction we have seen repeatedly in other layers of computing.
The user expresses intent.
The scheduler allocates resources.
Cursor Router is interesting because it applies that idea to the newest resource in the modern stack:
model intelligence can also be scheduled, measured, and allocated as capacity.
And once that happens, the question stops being which LLM is the best in the world.
The useful question becomes:
which model is right for this step, in this context, under this budget?
That is the problem model routers are beginning to solve.