 Capital de Tokens
What should an artificial intelligence system do when it is not sure about its answer?
Most current systems have a fairly crude solution: generate an answer anyway.
We can ask them to “think more,” increase the reasoning budget, or put several agents in charge of reviewing the result. But that decision is usually defined from outside: by a prompt, a fixed configuration, or an architecture designed in advance.
Recent work on artificial metacognition proposes a much more interesting alternative: have the system itself produce explicit signals about its state and use those signals to decide how each problem should be processed.
This is not about turning an LLM into a conscious machine.
It is about building a control layer around the model.
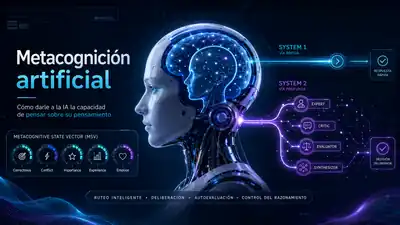
The idea was explained for a general audience in “How to give AI the ability to ‘think’ about its ‘thinking’”, based on work by Ricky J. Sethi, Charles Courchaine, Hefei Qiu, and collaborators. In August 2026, the team also published an explicit implementation of the framework for LLM ensembles, with routing between fast and deliberative processing and specialized roles inside a multi-agent system.
The truly important part of the work is not the phrase self-awareness.
It is this architecture:
LLM
 ↓
monitoring
 ↓
uncertainty / conflict / importance signals
 ↓
control policy
 ↓
routing
 ↓
fast answer / more reasoning / other agents / human
That looks less like “an AI thinking about itself” and much more like an intelligent runtime for reasoning.
Metacognition: thinking about thinking
In psychology, metacognition is usually described as the ability to monitor and regulate our own cognitive processes.
An everyday example is reading a page and realizing that, although we reached the end, we did not actually understand it.
That moment contains two different operations:
- Monitoring: “I am not understanding this.”
- Control: “I should reread it, change strategy, or look for another explanation.”
The framework tries to bring that separation into LLM-based systems.
It does not need to claim that the model “feels” confusion in the human sense. It only needs to produce variables useful enough for another component to act on them.
In engineering, that distinction is fundamental.
A thermostat does not need to feel cold to detect a temperature and turn on the heat.
Likewise, an agentic system does not need consciousness to detect signals associated with uncertainty or contradiction and spend more resources when the situation justifies it.
The central piece: Metacognitive State Vector
The framework introduces a Metacognitive State Vector, or MSV.
It is a five-dimensional vector designed to quantify signals describing the system’s metacognitive state:
| Dimension | What it tries to measure |
|---|---|
| Emotional Response | Whether the query has relevant emotional or sensitive content |
| Correctness Evaluation | How reliable the current answer or reasoning appears |
| Experiential Match | Whether the problem resembles situations the system recognizes well |
| Conflicting Information | Whether data, premises, or conclusions conflict |
| Problem Importance | How costly or important it would be to be wrong |
We can imagine it in simplified form as:
msv = {
    "emotion": 0.2,
    "correctness": 0.43,
    "experience": 0.35,
    "conflict": 0.81,
    "importance": 0.92,
}
The value is not in producing five pretty numbers for a dashboard.
The value appears when those numbers control execution.
For example:
if (
    msv["conflict"] > 0.7
    or msv["correctness"] < 0.5
    or msv["importance"] > 0.8
):
    route = "system_2"
else:
    route = "system_1"
Real thresholds can be much more sophisticated. But the architectural pattern is this: observe first, then decide how much reasoning to buy.
System 1 and System 2 as a compute policy
The researchers use the familiar distinction between System 1 and System 2 as inspiration for two processing modes.
System 1: the fast path
A simple, familiar, low-risk question can be solved with inexpensive execution.
query
  ↓
MSV
  ↓
low complexity / low conflict
  ↓
LLM
  ↓
answer
There is no need to convene five models, run three critiques, and synthesize four drafts to answer what 2 + 2 equals.
That would waste compute, tokens, and latency.
System 2: the deliberative path
When conflict, uncertainty, novelty, or importance rise, the system can activate a more expensive route.
query
  ↓
MSV
  ↓
uncertainty / conflict / high risk
  ↓
System 2
  ↓
Expert
  ↓
Critic
  ↓
Evaluator
  ↓
Synthesizer
  ↓
deliberated answer
The implementation described by the team uses LLM ensembles and specialized roles such as Domain Expert, Critic, Evaluator, Synthesizer, and Generalist.
In its latest demo, the group even shows role assignment based on agents’ metacognitive states and a visualization of how the MSV changes during deliberation.
This is more interesting as agent architecture than as philosophy
The word “metacognition” quickly invites questions about consciousness, self-awareness, or artificial minds.
But from an engineering perspective there is a more immediate interpretation.
Imagine a traditional software-agent flow:
Developer → Reviewer → QAEvery change passes through every stage.
It is safe, but potentially expensive.
Now add a metacognitive controller:
                         ┌───────────────► Developer
                         │                  trivial task
                         │
Task → Metacognitive ────┼───────────────► Developer → Reviewer
       Controller        │                  medium uncertainty
                         │
                         ├───────────────► Developer ↔ Critic → Reviewer
                         │                  high conflict
                         │
                         └───────────────► Developer → Reviewer → QA → Human
                                            high risk
Suddenly the workflow stops being a fixed chain.
It becomes a dynamic escalation policy.
That has enormous consequences for long-running agents.
An agent working for hours should not use its most expensive reasoning configuration for every decision. Nor should it treat every action as equally dangerous.
It can distinguish between:
- reading a file;
- renaming a variable;
- changing authentication;
- running a destructive migration;
- deploying to production.
Instead of configuring one reasoning level for an entire session, we could assign it per decision.
The MSV as a reasoning control plane
This is, to me, the most powerful interpretation of the work.
The architecture begins to look like a control plane.
In distributed systems, a control plane decides how infrastructure should behave. It does not necessarily process every packet or request: it maintains policies, observes state, and makes coordination decisions.
We can apply the idea to reasoning:
                ┌──────────────────────┐
                │ Metacognitive Plane  │
                │                      │
input ─────────►│ uncertainty          │
                │ conflict             │
                │ importance           │
                │ experience           │
                │ emotional/safety     │
                └──────────┬───────────┘
                           │
             ┌─────────────┼─────────────┐
             ▼             ▼             ▼
         fast LLM      deep model    agent ensemble
             │             │             │
             └─────────────┼─────────────┘
                           ▼
                        output
The innovation is no longer simply getting a model to reason better.
It is getting a system to decide when it needs to reason better.
And that difference could be decisive for agent economics.
Adaptive reasoning instead of maximum reasoning
Over the last few years, much of the improvement in reasoning models has been associated with spending more compute at inference time.
But a real system has constraints:
- latency;
- tokens;
- GPU;
- money;
- API limits;
- energy;
- tool availability;
- human intervention.
The question stops being only:
Which model reasons best?
And becomes:
What is the minimum amount of reasoning needed to correctly resolve this decision?
That shift turns reasoning into a resource that can be budgeted dynamically.
A hypothetical policy could work like this:
def choose_reasoning_budget(msv):
    risk = (
        0.35 * msv.importance
        + 0.30 * msv.conflict
        + 0.20 * (1 - msv.correctness)
        + 0.15 * (1 - msv.experience)
    )

    if risk < 0.25:
        return "fast"
    if risk < 0.55:
        return "standard"
    if risk < 0.80:
        return "deep"
    return "multi_agent_plus_human_gate"
The code is illustrative and not part of the paper.
But it shows why the idea is useful: metacognition can become a scheduler for intelligence.
From deterministic workflows to adaptive workflows
Many multi-agent systems today are still designed like this:
Planner
  ↓
Researcher
  ↓
Writer
  ↓
Critic
  ↓
Reviewer
Every task executes almost the same graph.
That has advantages: it is easy to understand, test, and observe.
But it also has a problem: it wastes work when the task is simple and may be insufficient when the task is exceptionally hard.
A metacognitive system would allow the graph to transform during execution.
simple
Task ──────────────► Worker ─────────► Done

uncertain
Task ─► Worker ─► Reviewer ──────────► Done

conflicted
Task ─► Expert ─► Critic ─► Evaluator ─► Synthesizer

high stakes
Task ─► Ensemble ─► Verification ─► Human approval ─► Action
That brings agents closer to a property we expect from good human teams: do not call a five-person meeting for every decision, but do not resolve a critical crisis with one improvised opinion either.
An important distinction: self-confidence is not calibration
This is where the most important technical problem appears.
An LLM can say:
I am 92% confident.That does not imply that, out of every hundred answers for which it reports 92% confidence, roughly 92 are correct.
For a confidence signal to be useful as a control component, it needs to be calibrated against real outcomes.
Otherwise, we can build a sophisticated controller on top of a defective signal.
The risk would be especially serious for high-impact decisions:
overconfident model
      ↓
MSV interprets “high correctness”
      ↓
System 1
      ↓
fast answer
      ↓
error that deserved deliberation
That is why the future of these systems will probably require combining model introspection with external signals:
- verifiers;
- tests;
- retrieval;
- consistency across models;
- real code execution;
- tool evidence;
- error history;
- empirical calibration;
- human approval when risk requires it.
Metacognition should not become another way of believing the model because the model says it is right.
It should become telemetry that can be checked against evidence.
Observability of reasoning
There is another interesting consequence.
If the system generates an MSV before and during execution, we can observe not only the final answer but also why it selected a particular strategy.
For example:
Query: "Should we deploy this change?"

Correctness: 0.58
Conflict:    0.76
Experience:  0.41
Importance:  0.93
Emotion:     0.05

Decision:
System 2 activated

Reason:
- high importance
- high conflict
- low experiential match
That is very different from a black box that simply answers.
For agentic systems, we could store those states alongside every execution:
trace_id
prompt
model
MSV_before
routing_decision
roles_activated
tools_used
MSV_after
verification_result
final_action
With enough traces, it becomes possible to ask questions such as:
- How many times did the system choose System 1 and fail?
- Which signal best predicts an error?
- In which domains is it overconfident?
- When does activating a critic actually improve the outcome?
- How much does each additional point of reliability cost?
At that point, metacognition stops being a psychological metaphor and starts looking like operational observability for agents.
And what about consciousness?
The work itself draws an important boundary: this framework does not demonstrate consciousness or human-like self-awareness in machines.
What it implements is a computational architecture for monitoring and regulation.
The difference matters.
We can name a variable self_awareness, but the name does not change what the software does.
An MSV can measure signals, trigger policies, and reorganize agents without any subjective experience behind it.
From a practical perspective, we also do not need to solve the philosophical problem of consciousness before this architecture becomes useful.
Autonomous systems urgently need mechanisms to:
- recognize uncertainty;
- detect contradictions;
- escalate decisions;
- allocate more compute when it is worthwhile;
- request external review;
- explain why they selected a route.
That would already be a significant advance.
What comes next: metareasoning
The researchers identify metareasoning as a future direction: not only evaluating the current state, but reasoning about the reasoning strategy itself.
The difference can be understood like this:
Reasoning:
"What is the answer?"

Metacognition:
"How reliable does my current process appear?"

Metareasoning:
"What is the best strategy for reaching a reliable answer with the available resources?"
An agent with metareasoning could choose between:
search the web
vs.
consult internal documentation
vs.
execute code
vs.
ask for another opinion
vs.
create a test
vs.
escalate to a human
And it could choose not only based on capability, but on expected cost and uncertainty reduction.
That moves us toward much less rigid agents.
The idea worth remembering
The headline “give AI the ability to think about its thinking” is attractive.
But there is a more useful technical interpretation:
make reasoning observable, measurable, and controllable.
An isolated LLM produces an answer.
A metacognitive system tries to know whether that answer deserves trust and decides which additional resources it needs before acting.
The evolution could look like this:
LLM
↓
LLM + tools
↓
agent
↓
agent + memory
↓
agent + verification
↓
agent + metacognitive controller
↓
adaptive reasoning system
Perhaps one of the major advances in agents will not simply be that models learn to think more.
It may be that we learn to build systems capable of deciding when to think more, how to do it, and when to stop trusting themselves.
That problem looks much closer to engineering than to science fiction.
Sources
- MSN article: “How to give AI the ability to ‘think’ about its ‘thinking’”
- Ricky J. Sethi / The Conversation: explanation of artificial metacognition, republished by Fast Company
- Courchaine, Sethi, and Qiu: “Implementation of a Metacognition Framework for Self-Awareness and Self-Regulation in Ensembles of LLMs”
- Metacognition Research project
- Multi-agent architecture and role-assignment demo
- The Web Conference 2026 paper