 Capital de Tokens
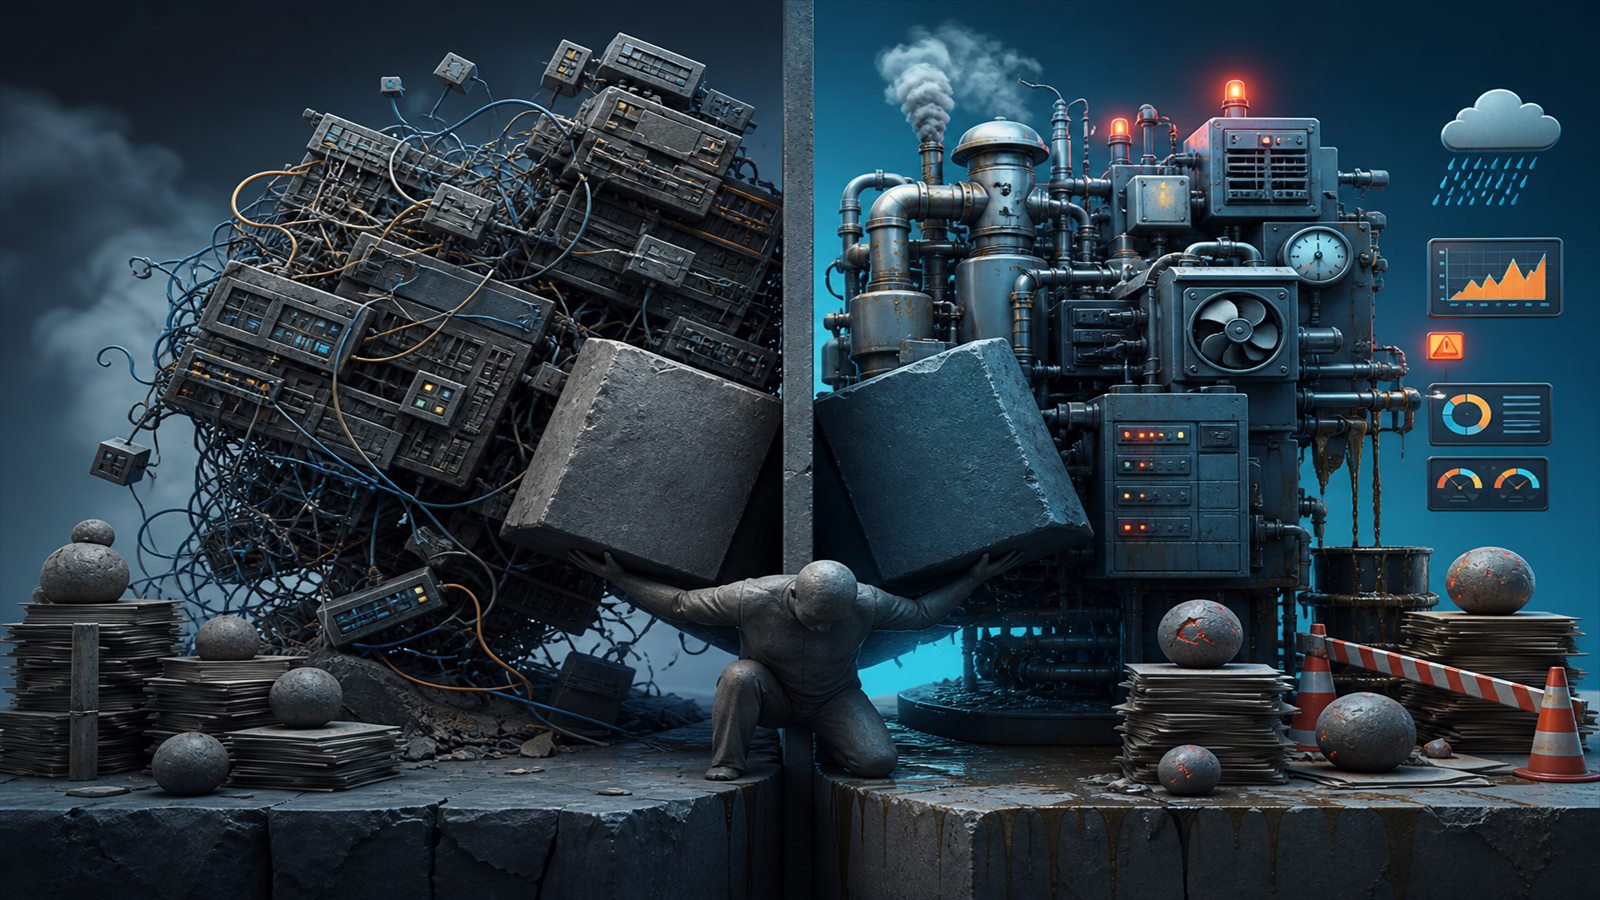
Technical debt vs operational debt: two different ways of paying interest
In software engineering we talk constantly about technical debt.
Duplicated code.
Architectures that are difficult to change.
Outdated dependencies.
Insufficient tests.
Internal APIs nobody wants to touch.
But there is another kind of debt that receives less attention and can be just as expensive —or more so— in real systems: operational debt.
The simplest way to distinguish them is this:
Technical debt = how difficult the system is to change.
Operational debt = how difficult the system is to keep running.
Both generate interest.
The difference is where we pay it.
Technical debt: paying more every time we change the software
Technical debt appears when a design, architecture, or implementation decision makes the system harder to evolve.
For example:
New feature
   ↓
must modify 7 modules
   ↓
nobody knows what may break
   ↓
3 days of regression work
The problem is not necessarily that the software is down.
It may work perfectly in production.
The problem appears when we try to modify it.
Classic examples include:
- duplicated code;
- highly coupled modules;
- lack of tests;
- inconsistent internal interfaces;
- legacy dependencies;
- workarounds turned into permanent architecture;
- hardcoded configuration;
- data models that are difficult to extend;
- a codebase where only one person understands certain areas.
We can think of technical debt as a tax on future development.
simple change
   ↓
accumulated complexity
   ↓
more time
   ↓
more risk
   ↓
more testing
   ↓
more cost
The “interest” is paid every time we touch the system.
Operational debt: paying more every time we operate the system
Operational debt appears when a system may be well built but operating it requires too much manual work, tribal knowledge, or fragile procedures.
For example:
Deploy
   ↓
SSH into server
   ↓
edit config
   ↓
copy files
   ↓
restart service
   ↓
inspect logs manually
The code can be clean.
The tests can be excellent.
The architecture can be well modularized.
But if deploying, recovering, monitoring, or diagnosing the system requires manual rituals, there is operational debt.
Common examples include:
- manual deployments;
- manually configured servers;
- infrastructure not represented as IaC;
- secrets copied manually;
- certificates someone must remember to renew;
- alerts full of false positives;
- dashboards nobody knows how to interpret;
- lack of runbooks;
- backups that exist but have never been tested;
- disaster recovery that exists only in an old document;
- slow or unknown rollback procedures;
- operational knowledge owned by one person;
- insufficient observability.
Here the interest is not paid while implementing a feature.
It is paid during:
deployments
incidents
migrations
on-call
recoveries
infrastructure changes
The difference in one table
| Technical debt | Operational debt | |
|---|---|---|
| Accumulates mainly in | code, architecture, design | operations, infrastructure, processes |
| Makes it harder to | change the system | keep the system running |
| Interest appears during | development and maintenance | deployments, incidents, and operations |
| Example | changing one feature breaks five modules | every deployment requires ten manual steps |
| Typical symptom | “nobody wants to touch that area” | “only Juan knows how to do that procedure” |
A useful question for distinguishing them is:
Does the pain appear when I try to change the software?
→ probably technical debt

Does the pain appear when I try to operate it?
→ probably operational debt
A system can have little technical debt and a lot of operational debt
Imagine a reasonably well-designed API:
API
├── clear modules
├── good tests
├── updated dependencies
└── reasonable architecture
But production works like this:
release
  ↓
build manually
  ↓
upload artifact
  ↓
log into server
  ↓
update variables
  ↓
restart service
  ↓
check logs
The codebase may be healthy.
Operations are not.
That is operational debt.
The opposite can also happen
A team may have automated operations extremely well:
commit
  ↓
CI
  ↓
tests
  ↓
artifact
  ↓
deploy
  ↓
health checks
  ↓
automatic rollback
But underneath there may be a monolithic, highly coupled architecture that is difficult to change.
The operational platform is excellent.
The product accumulates technical debt.
The most dangerous case: when the two debts reinforce each other
In production, technical debt and operational debt rarely remain completely separate.
One can produce the other.
For example:
application without clear health checks
            ↓
no reliable health signal
            ↓
operations checks logs manually
            ↓
a manual procedure is created
            ↓
operational debt
The origin was technical.
The cost becomes operational.
Another example:
manually configured infrastructure
            ↓
nobody knows exactly what exists
            ↓
developers are afraid to change it
            ↓
workarounds accumulate
            ↓
technical debt
Here operational debt ends up creating technical debt.
The cycle can become self-sustaining:
technical debt
      ↓
harder to automate
      ↓
operational debt
      ↓
more fear of changing things
      ↓
more workarounds
      ↓
more technical debt
Observability is a place where both often mix
Monitoring systems are a perfect example.
Suppose we have:
20 health checks
30 alert rules
several dashboards
Action Groups
maintenance scripts
Technical debt can appear as:
- legacy resources;
- duplicated configuration;
- inconsistent naming;
- old APIs;
- rules that are difficult to reuse;
- templates nobody wants to touch.
Operational debt can appear as:
- alerts nobody knows how to map to a service;
- lack of ownership;
- manual portal changes;
- no runbook;
- notifications that are never tested;
- dashboards that show green while the alert channel is broken.
An important property appears here:
An observability system can “work” technically and still be operationally indebted.
A real example: Azure URL Ping Tests → Standard Tests
A recent case documented at Capital de Tokens illustrates this intersection very well.
Microsoft is retiring the classic Application Insights URL Ping Tests, which forces teams to migrate them to Standard Tests.
The complete analysis is here:
Migrating Azure Application Insights URL Ping Tests to Standard Tests without losing alerts
At first glance, it looks like a purely technical migration:
legacy webtest
     ↓
standard webtest
That is the most visible part of the technical debt: a legacy technology must be replaced.
But the migration showed that the real problem was much broader.
We also had to preserve:
alert rules
Action Groups
notifications
secret handling
telemetry
rollback
runbook
That is where operational debt appears.
Because creating the new Standard Test does not guarantee that:
- the alert points to the correct resource;
- Azure Monitor scope is coherent;
- the Action Group remains connected;
- someone actually receives an email when it fails;
- there is a fast rollback path.
That is why the procedure ended up looking like this:
DISCOVER
   ↓
INVENTORY
   ↓
WHAT-IF
   ↓
DEPLOY DISABLED
   ↓
VERIFY
   ↓
ENABLE
   ↓
MOVE ALERTS
   ↓
TEST FAILURE PATH
   ↓
KEEP ROLLBACK
Replacing the resource was technical debt.
The need to make the full procedure explicit and verifiable was operational debt.
An alert that is never tested is debt too
There is a particularly quiet form of operational debt: configuration we assume is correct because it has never failed.
For example:
Availability Test ✅
Alert Rule        ✅
Action Group      ✅
Everything appears configured.
But we have never forced a failure condition.
So we do not actually know whether:
endpoint fails
   ↓
test detects failure
   ↓
alert rule fires
   ↓
Action Group executes
   ↓
operator receives notification
In the Standard Tests migration, the solution was to trigger a controlled synthetic failure and verify the complete chain.
That kind of test reduces operational debt because it turns assumed knowledge into demonstrated knowledge.
IaC reduces operational debt, but not necessarily technical debt
Infrastructure as Code is often one of the best tools against operational debt.
Instead of:
“go into the portal and change these six things”we can have:
repo
  ↓
template
  ↓
What-If
  ↓
review
  ↓
deploy
That improves:
- reproducibility;
- auditing;
- rollback;
- review;
- automation;
- knowledge transfer.
But poorly designed IaC can also accumulate technical debt.
An 8,000-line giant template with duplicated logic can be perfectly reproducible and still be extremely difficult to maintain.
Automation does not automatically eliminate technical debt.
Runbooks are operational code
A useful way to think about runbooks is to treat them as part of the product.
If a critical incident depends on someone remembering:
first run A
then change B
if C appears do D
but only in west production
we have operational debt.
A good runbook turns tribal memory into an explicit procedure:
trigger
  ↓
diagnosis
  ↓
action
  ↓
verification
  ↓
rollback
And the natural next step is to automate whatever can be automated safely.
We can think of the evolution like this:
tribal knowledge
      ↓
documentation
      ↓
runbook
      ↓
script
      ↓
pipeline
      ↓
policy / automation
Each step reduces dependence on human memory.
How to detect technical debt
Useful questions include:
- does a small change require modifying too many parts?;
- are there modules nobody wants to touch?;
- are tests too fragile to support refactoring?;
- are there dependencies blocking upgrades?;
- is logic duplicated everywhere?;
- does the current design regularly force new workarounds?
If the answer is yes, we are probably paying technical interest.
How to detect operational debt
Other useful questions:
- how many manual steps does a deployment require?;
- how many procedures depend on one specific person?;
- can we reconstruct production from code?;
- have we tested our backups recently?;
- have we tested our alerts end to end?;
- do we have a known and tested rollback?;
- can we explain who owns every alert?;
- do we know exactly what to do during an incident at 3 AM?
If many answers are “no,” operational debt probably exists.
Not all debt is bad
The word debt can make every shortcut sound wrong.
Not necessarily.
A startup may consciously decide:
today: partially manual deploy
because:
we need to validate the product
before investing a week in automation
That can be perfectly rational.
The financial analogy works well here.
Taking on debt is not necessarily bad.
The dangerous combination is:
take on debt
   +
do not measure it
   +
do not repay it
   +
keep accumulating interest
The important question is whether the debt is deliberate and visible.
A practical way to manage both together
We can maintain two separate backlogs.
Technical debt backlog
refactors
upgrades
architecture
interfaces
simplification
tests
Operational debt backlog
deployment automation
IaC
runbooks
alert quality
backup verification
rollback
incident tooling
ownership
Separating them prevents operational debt from disappearing into a generic category of “technical stuff.”
It also helps prioritization.
A refactor may reduce development cost over the next six months.
Automating rollback may reduce the impact of an incident tomorrow.
Both matter, but they optimize different risks.
The idea worth remembering
When someone says a system has a lot of debt, it is worth asking:
debt for changing it?
      or
debt for operating it?
Because they are different problems.
We can summarize them like this:
TECHNICAL DEBT
“every change costs too much”

OPERATIONAL DEBT
“every operation costs too much”
And in mature systems we probably need to watch both as engineering-health metrics.
The best software is not only software that works today.
It should also be reasonably easy to change tomorrow and to keep running in the meantime.
That is the difference between paying technical interest and paying operational interest.